DeepSeek-V4.1-Flash: Frontier Agents on a Smaller Memory Budget
21 September 2026
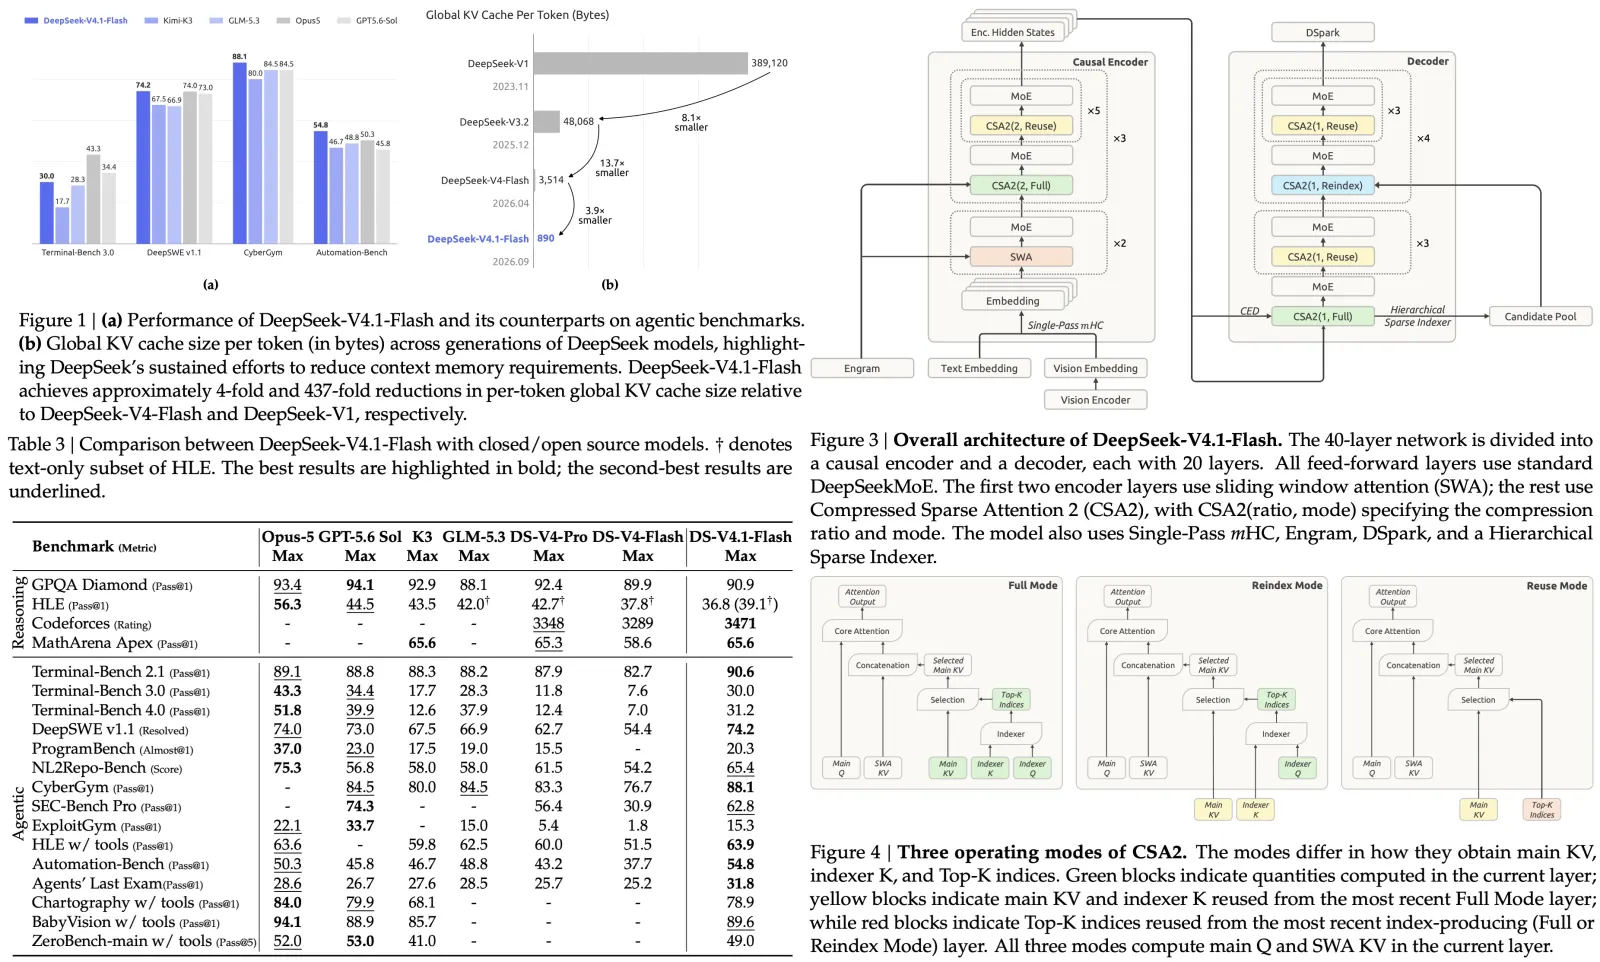
DeepSeek-V4.1-Flash is a 552B multimodal MoE model that attacks KV cache cost along all three of its multiplicative dimensions at once, then redesigns prefill and cache persistence around the result. It activates 8B parameters per token during prefill and holds 890 bytes of global cache per token.